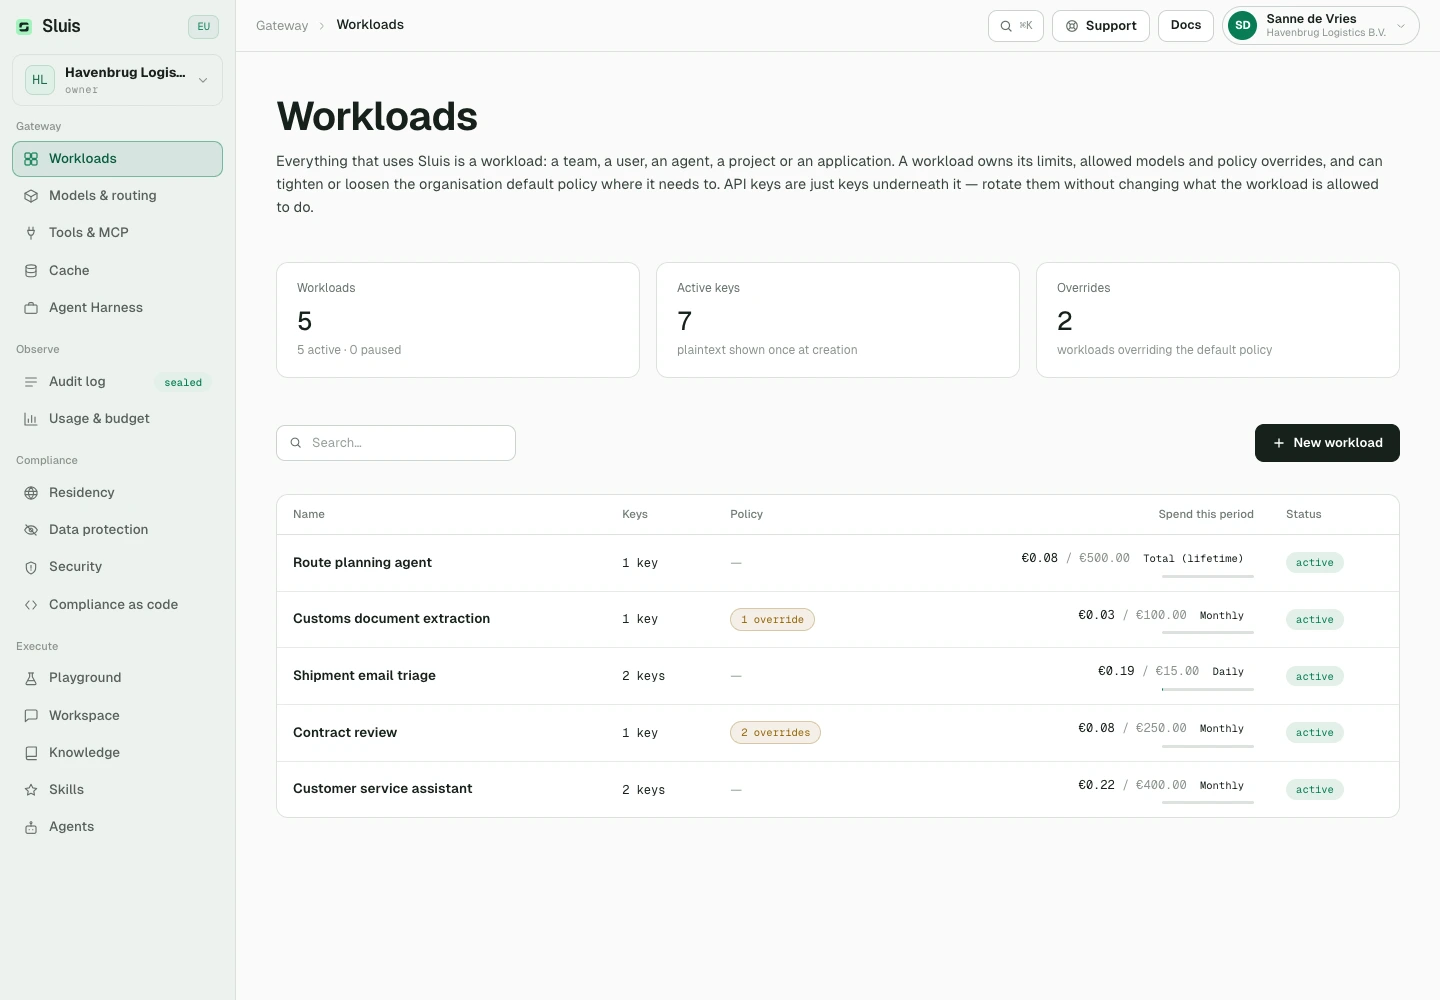
Workloads
A workload owns the settings for a team, user, agent or application. API keys are credentials underneath it.
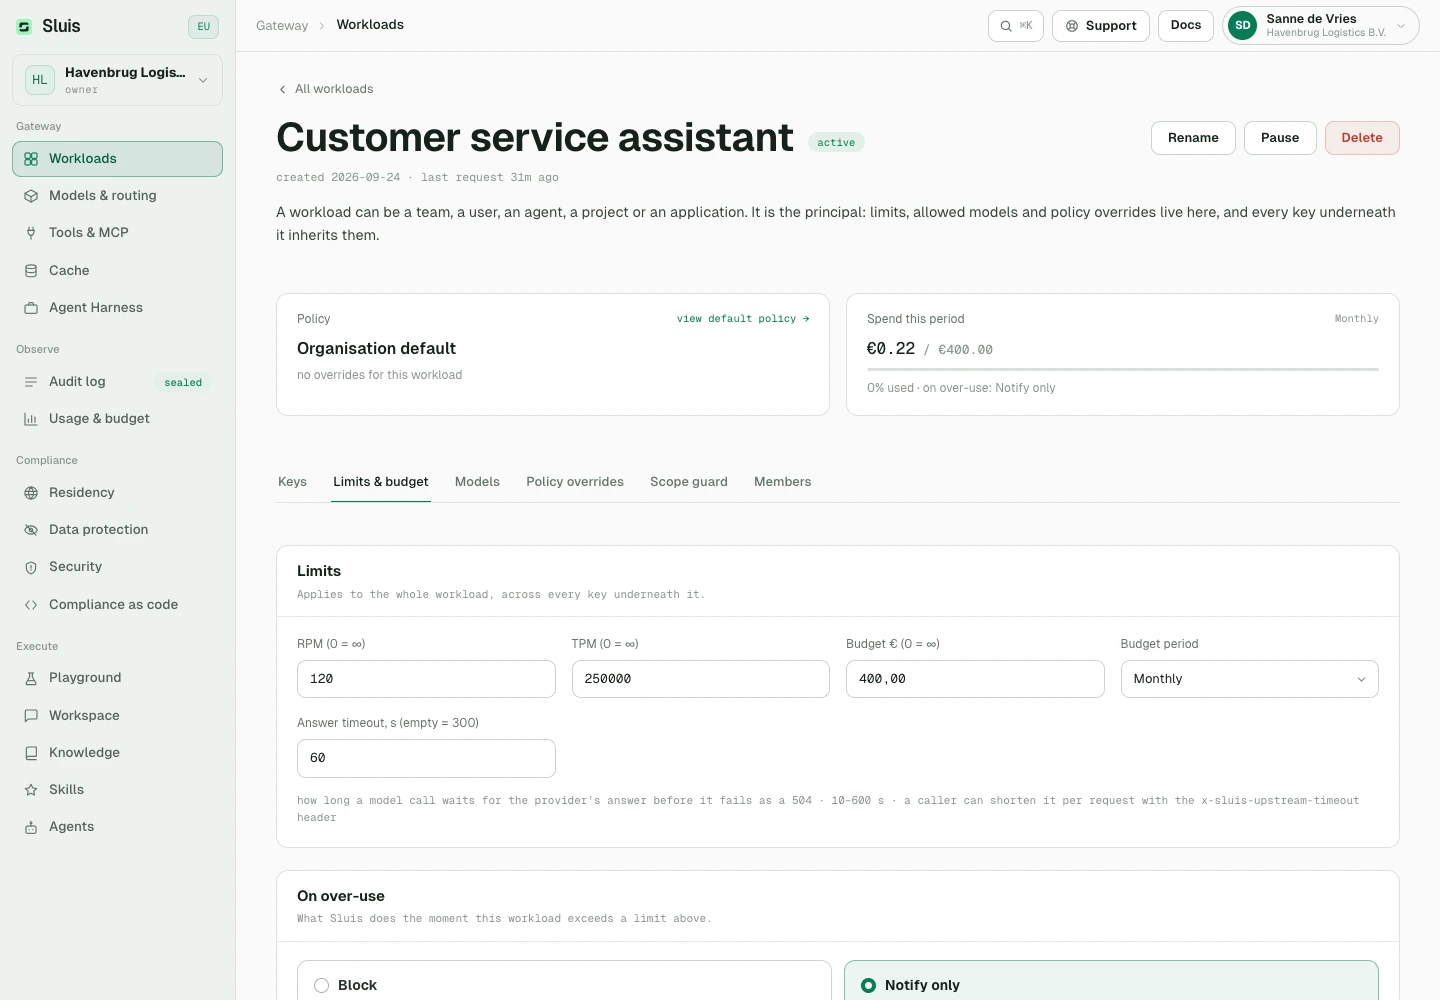
Set allowed models, requests and tokens per minute, and a daily, monthly or total budget. Choose block to stop over-budget calls (402), or notify to let them continue.
Under Limits & budget, the answer timeout sets how long a model call waits for the provider's answer: 10 to 600 seconds, 300 by default. A call without an answer in time fails with 504 and is not replayed, because the provider may still be working on it. A caller can shorten the timeout per request with the x-sluis-upstream-timeout header, never extend it. A streamed answer that has started is not cut by it; only 600 seconds of silence mid-stream end it.
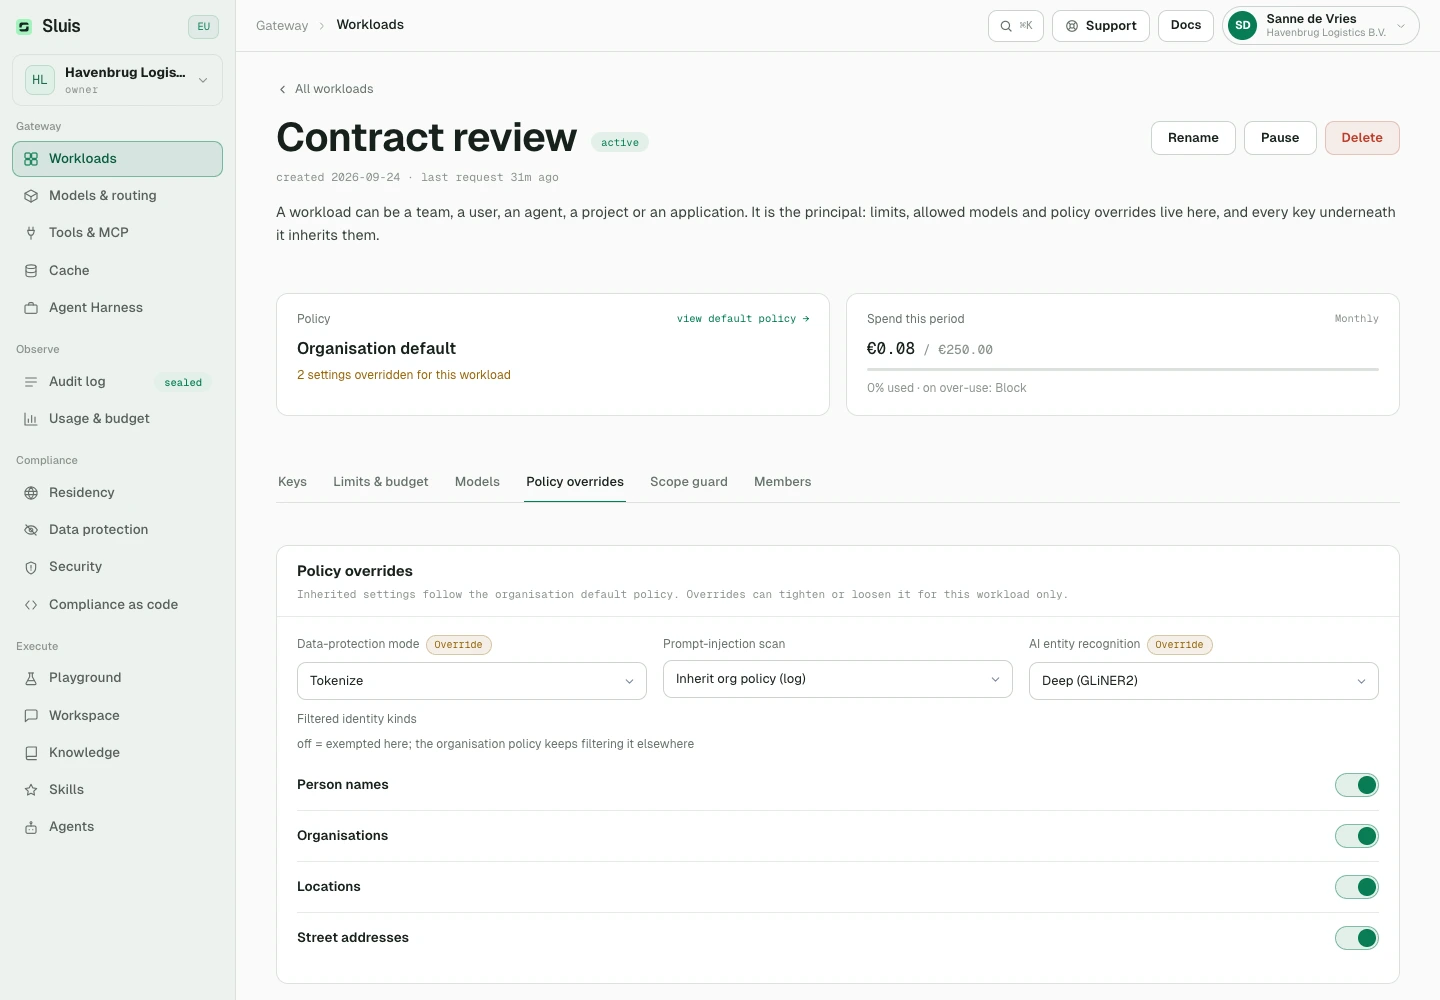
An empty option_overrides inherits organisation defaults. Pausing refuses requests (403) without revoking credentials. Rotate keys without changing the workload’s policy.
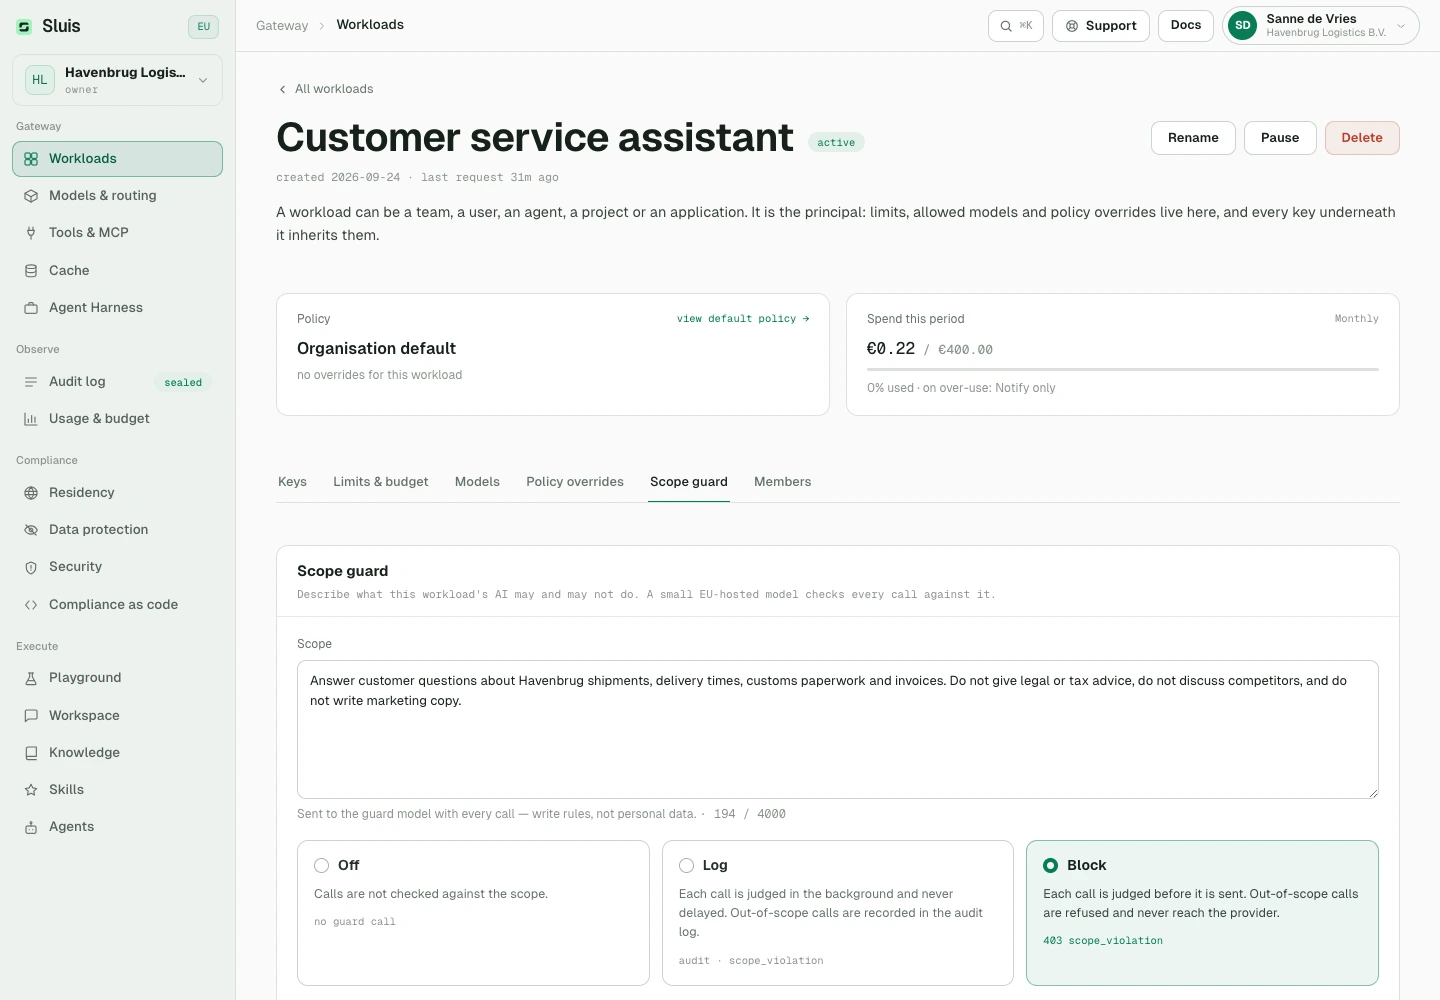
The scope guard checks every model call made with the workload's keys (embeddings excepted) against a scope you write in plain language: what this workload's AI may and may not do, up to 4,000 characters. A small EU-hosted model (Mistral Small) judges each call after data protection, on the text the provider would receive. off skips the check. log judges in the background without delaying the call and records out-of-scope calls in the audit log. block waits for the verdict and refuses an out-of-scope call with 403 scope_violation before it reaches the provider; if the check cannot complete, the call is refused with 503. Each check is a separate audit receipt, billed at the model's token price, and your residency policy must allow that model.